Critical equipment rarely fails without warning. More often it sends small signals for weeks: a breakdown that keeps coming back, a service that runs longer each time, a meter reading that creeps past its usual pattern. The trouble is that these signals sit in different places, and nobody sees them together.
Extending the life of an asset is mostly about gathering that evidence in one place and deciding calmly when to step in, before the failure decides for you.
Start with the history you already have
Every repair, service visit, part change and inspection tells part of the story of an asset. When that history lives in one record, you can answer simple but valuable questions. How often has this unit failed? What did we do each time? Is the same fault coming back after every fix? An asset that has needed the same repair three times is telling you the repair is not addressing the cause.
Repeat-fault reporting is one of the most practical tools here. It brings recurring problems to the top so that a root cause conversation happens before the fourth call-out, not after.
Two numbers worth watching: MTBF and MTTR
Mean time between failures, or MTBF, tells you how long an asset typically runs between breakdowns. Mean time to repair, or MTTR, tells you how long it takes to get it working again. Read together, they show whether an asset is becoming less dependable or merely slow to fix.
A falling MTBF suggests wear or a recurring cause. A rising MTTR may point to hard-to-get parts, a missing procedure or a lack of the right skills. Each calls for a different response, which is why it helps to see both. Total cost of ownership and overall equipment effectiveness add the financial and output picture, so replacement decisions rest on more than a feeling.
Meter readings, health scores and calibration
Run hours, cycles and other meter readings show how hard an asset has actually worked, which is often a better guide to wear than the calendar. A lift that is lightly used does not age like one that runs all day. Meter readings let service intervals follow real usage.
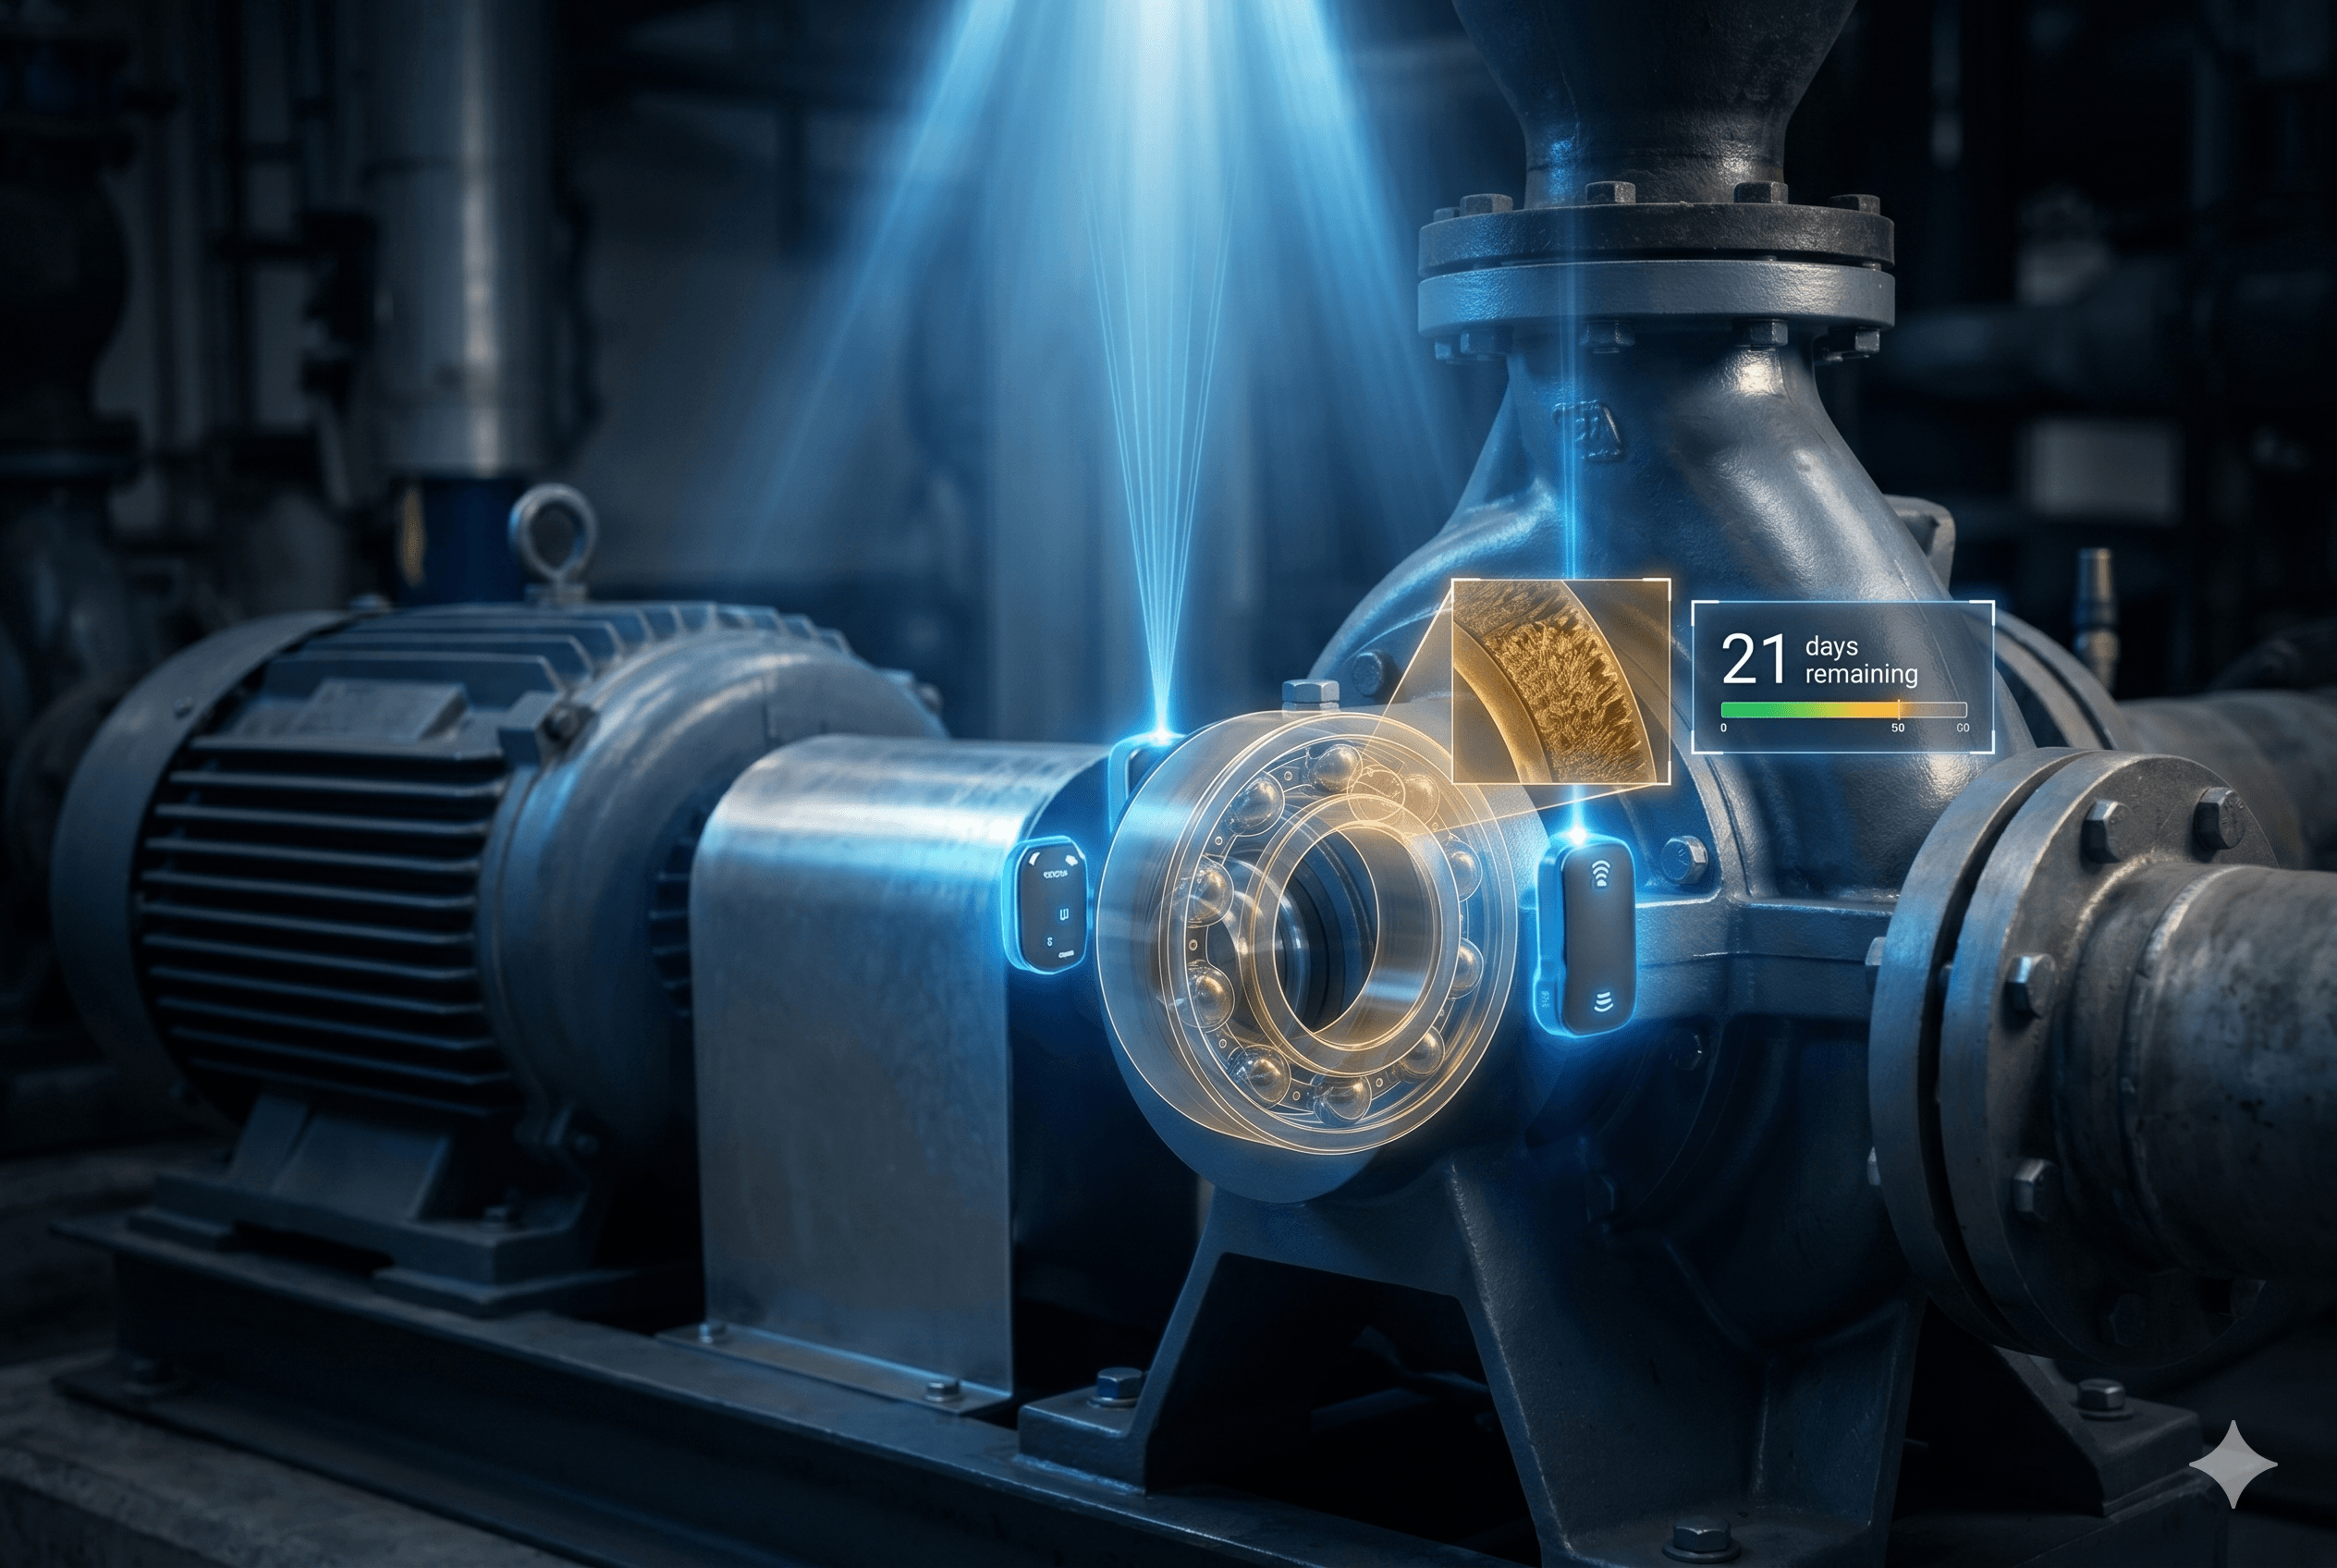
A health score gives a quick, comparable view across many assets. It draws on the recorded history, and it helps you decide where to look first. It is a prompt for attention, not a verdict. A low score is a reason to inspect, review the repair record and talk to the technician who knows the machine.
For instruments and measuring equipment, calibration records add another angle. If an instrument drifts further from its tolerance each time it is checked, that pattern is worth acting on before it affects product quality or compliance.
Deciding when to intervene
Intervening too early wastes money and downtime. Intervening too late costs far more. A sensible approach is to agree a few triggers for each critical asset: a number of repeat faults within a period, a health score falling below a set level, a meter reading reaching a limit, or a calibration result outside tolerance. When a trigger is hit, someone reviews the asset and decides whether to repair, adjust the plan, overhaul or replace.
Keep it practical. Not every asset needs this attention. Start with the ten or twenty items that would hurt most if they stopped.
Review these triggers regularly with your technicians and contractors. They often know which units are quietly difficult, and their knowledge is worth recording against the asset so it is not lost when people move on. A short note after each visit, linked to the equipment, soon builds a more useful picture than memory ever could.
Over time, this habit also makes budget conversations easier. When you can show the repair record, the repeat faults and the running cost of an ageing unit, a case for overhaul or replacement is far easier to put to an owner or finance team.
How FacilityFlow helps
FacilityFlow keeps the full history of each asset together: work orders, service history, meter readings, health logs and calibration events. It reports MTBF, MTTR and repeat faults per piece of equipment, calculates OEE and total cost of ownership, and recalculates an equipment health score every 6 hours. Meter-based schedules let servicing follow actual usage, and calibration schedules track as-found and as-left results against tolerances.
These features are rule-based and transparent, so your team can see why an asset is flagged. If you would like to see how this could work on your critical equipment, we would be happy to arrange a demo.
